
We started this project out of curiosity about the phase transition in neural networks, from memorization to generalization, which offers a rare chance to isolate a solution and watch it form. A lot of work has studied grokking through the geometry of its representations and through its optimization and loss landscapes. One recurring observation is that when a network groks, the effective rank of its weight matrices often falls as test accuracy jumps. We expected that forcing low rank in the weights from the start would speed grokking up. It didn't.
So we asked whether this rank compression causes generalization or is a consequence of it. We trained a mean-field MLP and a one-layer transformer on modular arithmetic and tested this with interventions and negative controls.
Key findings
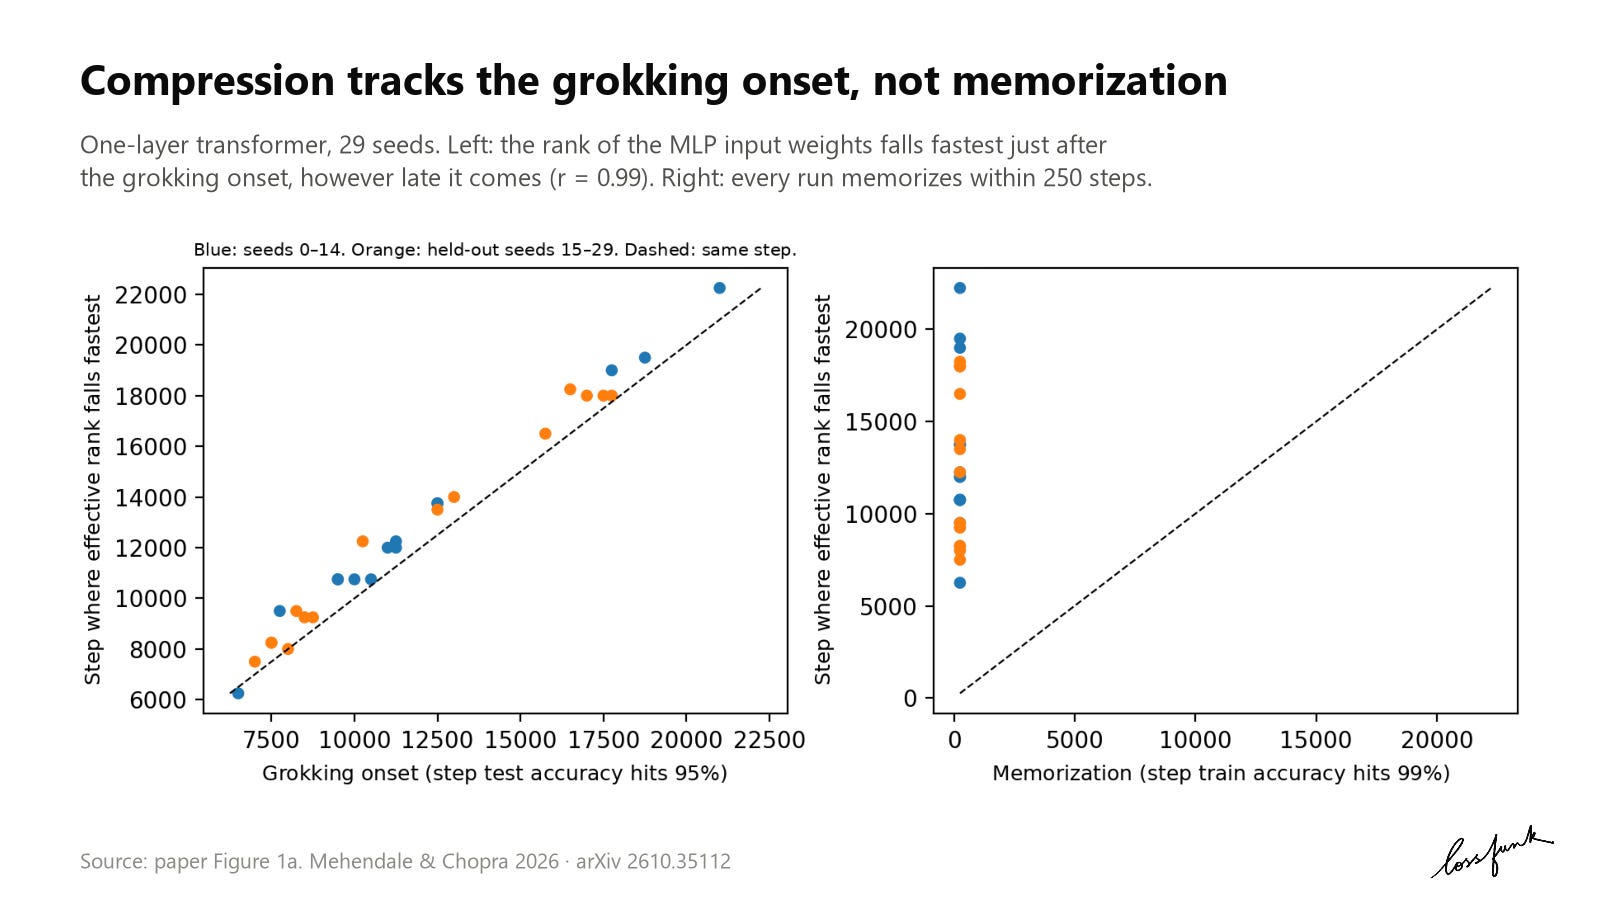
Compression tracks the grokking onset, not memorization. Every transformer memorizes its training set within 250 steps, while grokking onsets range from step 6,500 to 21,000. The steepest drop in effective rank lands about 900 steps after the onset, however late it comes (Pearson r = 0.99).
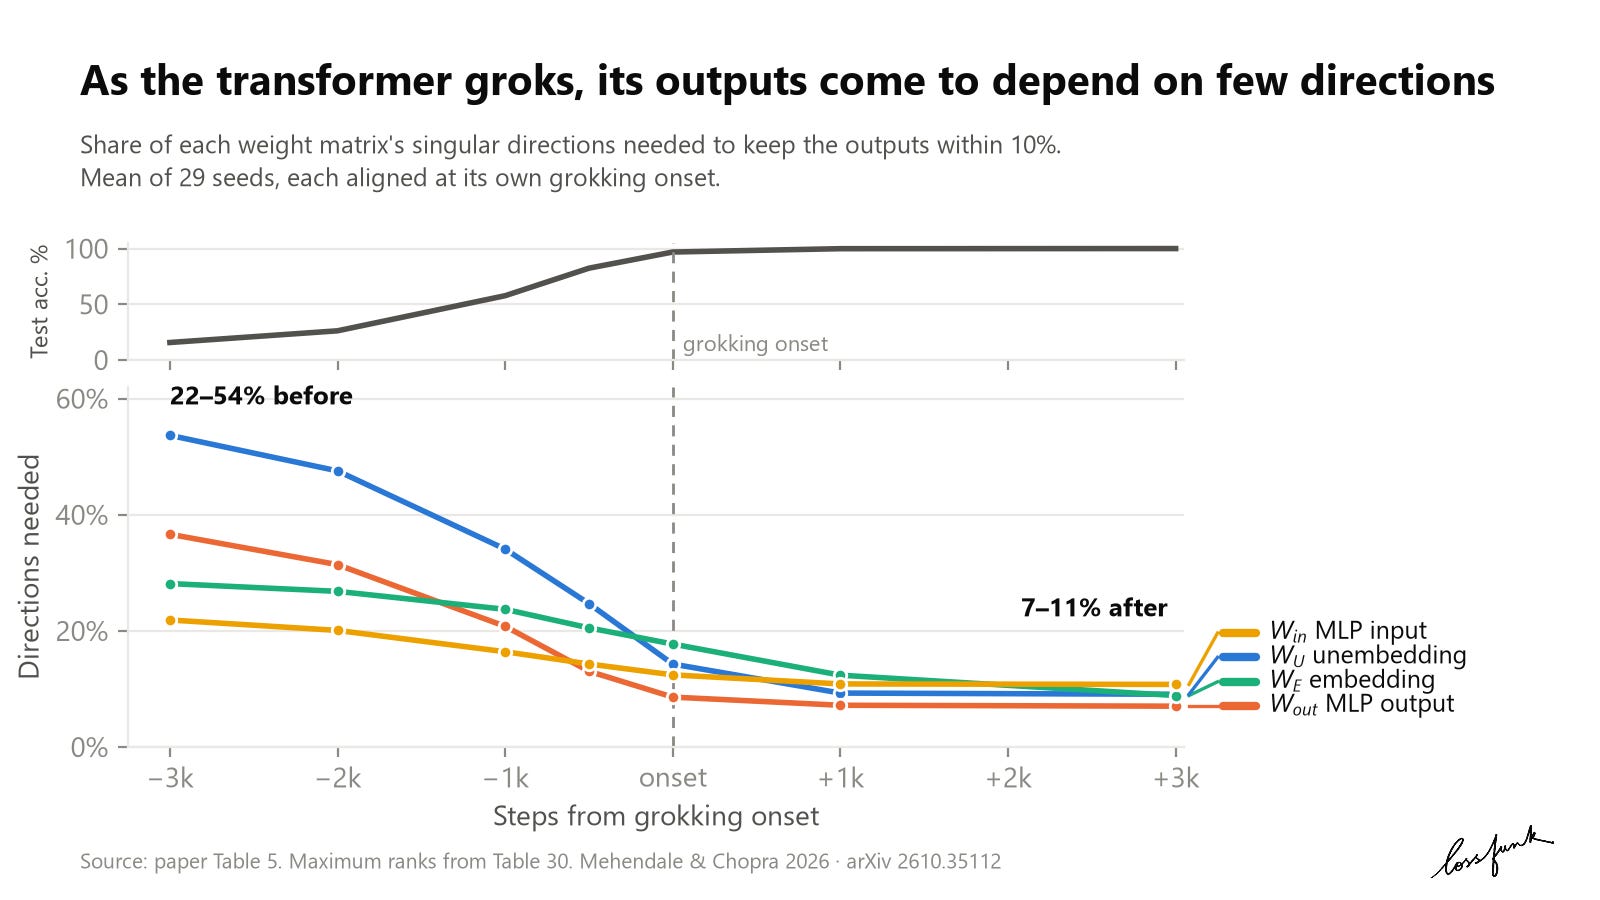
Subspace Crystallization. In the transformer, the share of each weight matrix’s directions that the outputs depend on falls from 22–54% to 7–11% over the transition.
Imposing low rank does not reliably speed grokking up. Against a factorized full-rank control, no rank cap reliably brings the onset forward. Most delay grokking or stop it. Capping the embedding’s rank stops 15 of 20 runs from grokking.
Compression seems to be a signature of grokking rather than its cause.
The question
Grokking is memorization followed by delayed generalization. For modular arithmetic we already know what the network computes: a sparse Fourier algorithm, built through phases of memorization, circuit formation and cleanup (Nanda et al., 2023).
Why the delay happens in the first place is less settled. Several explanations point to a slow pull toward simpler solutions, such as smaller weight norms (Liu et al., 2023) or more efficient circuits (Varma et al., 2023). Together with the fall in effective rank, that makes rank compression a natural suspect. We asked two questions.
Q1. Does rank compression cause grokking, or follow it?
Q2. Does the learned solution lie in the span of a few leading directions of each weight matrix?
The usual evidence cannot settle these, for three reasons.
Compression is usually seen after both memorization and the rise in test accuracy, so it is unclear which one it follows.
Timing alone cannot show cause. That needs interventions.
Accuracy hides the margin. Truncating a weight matrix until test accuracy drops only checks which output is largest. The margin is the gap between the correct output and the largest wrong output. As margins grow, more directions can be deleted before any prediction flips, so a count can fall even though the outputs still depend on those directions.
Setup
The main task is (a+b) mod 97, replicated on ab mod 97 and (a+b) mod 113. The MLP uses a quadratic activation and mean-squared error, whereas the transformer uses cross-entropy and weight decay. As negative controls we use MLPs trained on random labels and 7 transformer runs that memorize but never grok.
The grokking onset is the first step with a test accuracy of at least 95%. The memorization step is the first step with training accuracy of at least 99%.
Counting directions
We mainly rely on a geometric measure known as the effective rank of a matrix. A matrix whose k non-zero singular values are equal has effective rank k.
To determine the number of directions a solution requires, we keep only a weight matrix’s top k singular directions and leave the rest of the network unchanged.
d₀.₉₉: the fewest top directions that keep 99% of the test accuracy.
dₒᵤₜ: the fewest top directions that keep the network’s outputs within 10%.
d₀.₉₉ can fall simply because margins grow. However, dₒᵤₜ does not depend on the margin. We call a narrowing of dₒᵤₜ subspace crystallization. The 10% tolerance is a choice. At 5%, the MLP’s counts tell the same story.
Four stages of MLP training
The rates of change of ER and test accuracy split the MLP’s training into four stages. In memorization, training accuracy reaches 97.8% by step 8,000 while test accuracy stays below 5%. The grokking transition follows, with the onset at step 12,633 ± 297. In consolidation, effective rank stays near its maximum while the margin grows. In late compression, effective rank falls steadily (99% of which happens after the onset). In the MLP, rank grows during memorization and starts to fall only once test accuracy has risen.
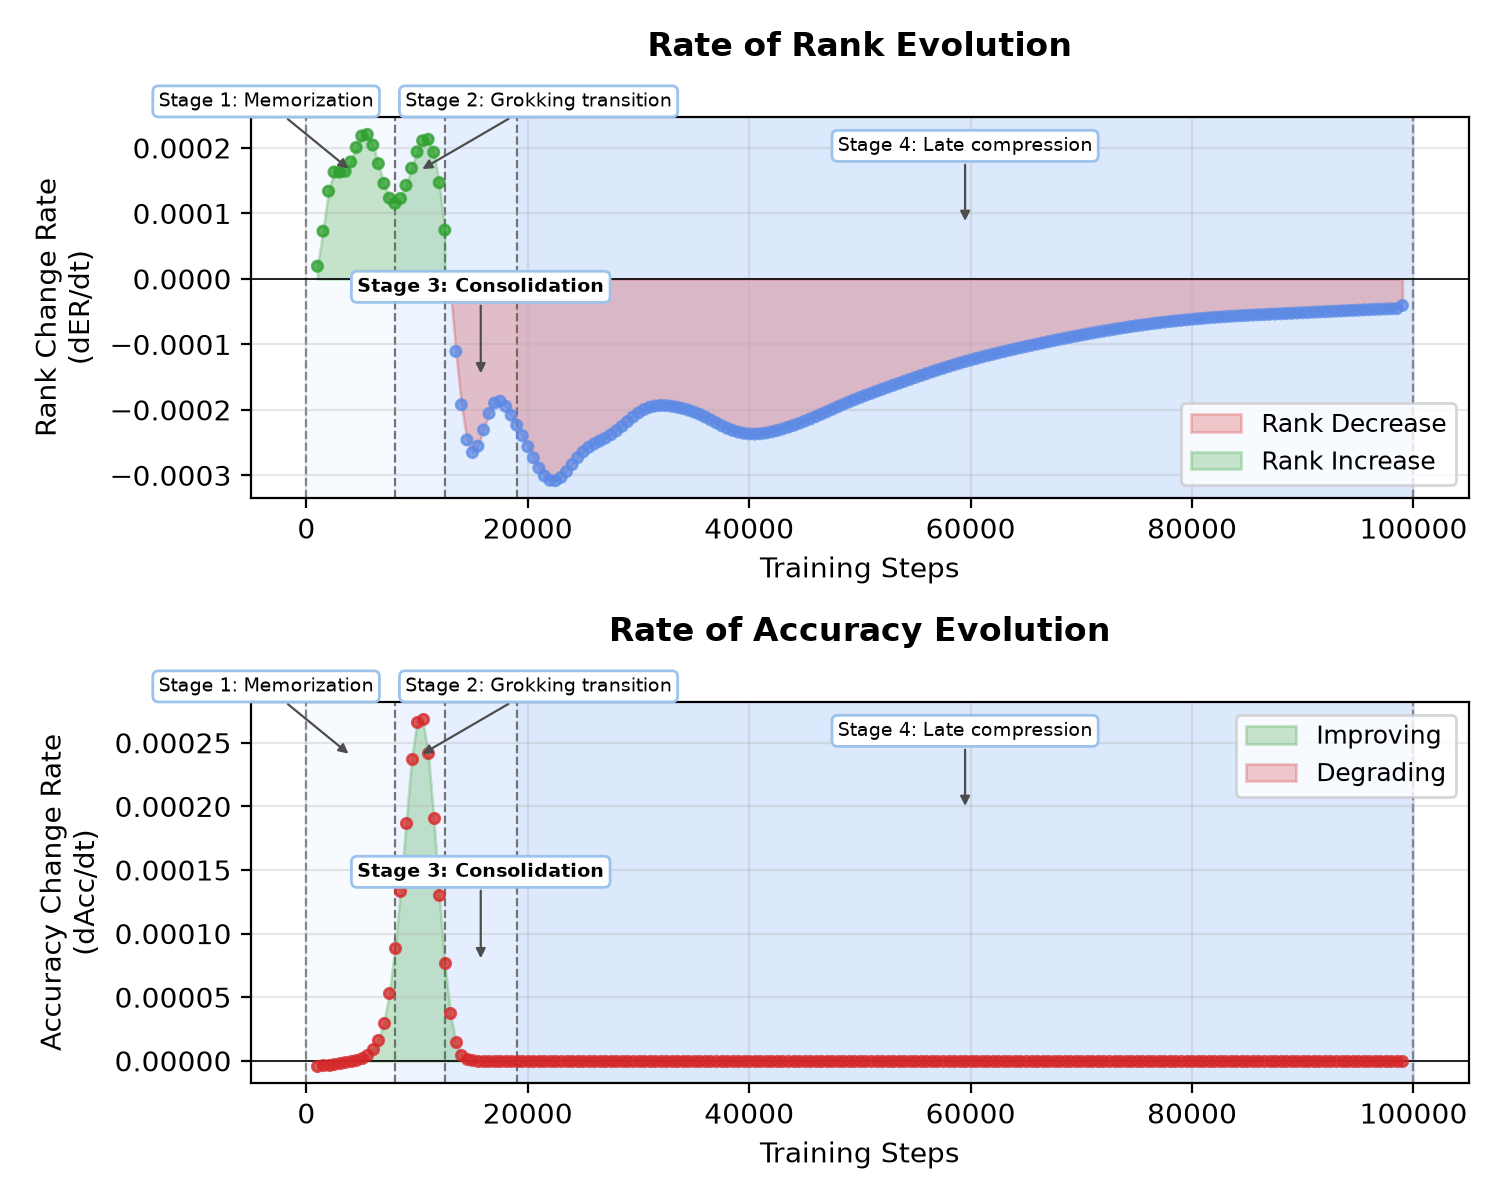
Effective rank rises slightly in the first two stages, from about 115 to 116 of 128. We think this is because both memorizing and the MLP’s Fourier solution spread across nearly all directions, so nothing concentrates the spectrum until the leading directions start to grow.
Finding 1: Compression tracks the grokking onset
All transformers memorize their training set within the first 250 steps, yet their onsets range from step 6,500 to 21,000. Weight decay initially shrinks the random initialization, which by itself lowers the effective rank of the MLP input weights, so we measure compression only after step 4,000. A second, sharp drop follows. The step where it is steepest lands shortly after the onset, however late the onset comes. Measured from the memorization step instead, the same drops scatter far more widely. If compression followed memorization, these drops would cluster at a fixed step.
Networks that memorize without grokking compress far less. The ER of the transformer’s MLP input weights falls by about 60% in runs that grok, but only by 15–23% in the seven runs that memorize and never grok. The MLP model shows the same gap: 10.5% in grokked networks against 1.1% in networks trained on random labels, even though those reach 90% training accuracy.
Here’s the catch. Six of the seven non-grokking transformers used weaker weight decay (0.1 or 0.3), which could by itself explain part of the difference. Comparing runs at the same training step gets around this. Before their own onset, grokked seeds have about as many directions as the one non-grokking run at weight decay 1.0. After it, they have far fewer.
Compression does not start before test accuracy rises
In the MLP, compression starts after the onset in all 15 seeds, with a mean lag of 6,367 ± 3,248 steps (one-sided t = 7.59, p = 1.3 × 10⁻⁶). Granger tests agree: changes in test accuracy predict changes in effective rank in all 15 seeds, and the reverse holds in at most 6.
In the transformer, compression is part of the transition itself. The second drop begins 1,888 ± 992 steps before the onset, but only after test accuracy has already reached 10% in 28 of 29 seeds. It is steepest at 905 ± 506 steps after the onset, and 63% of it happens after.
Replication on held-out seeds and tasks
We fixed the timing measures on seeds 0–14 and then tested them on new runs we hadn’t looked at. On 15 held-out transformer seeds, the steepest decrease came 850 ± 524 steps after the onset (14 of 15 seeds, the fifteenth at the onset). On ab mod 97 and (a+b) mod 113, the MLP’s compression followed the onset in all 30 runs. With a Bonferroni correction over all nine tests, every test but one remains significant.
Finding 2: subspace crystallization
With a checkpoint every 250 steps and each seed aligned at its own onset, we can watch dₒᵤₜ narrow while test accuracy rises. 3k steps before the onset, at 16% test accuracy, dₒᵤₜ is 22–54% of each matrix’s directions. At the onset it is 9–18%, and 3k steps later it is 7–11%.
It coincides with cleanup
The narrowing lines up with the cleanup phase of Nanda et al. (2023). Their restricted loss, which keeps only the key-frequency components of the logits, is halfway down 1,966 ± 647 steps before the onset, as the generalizing circuit forms. Their excluded loss, which removes those components, is halfway up 1,026 ± 646 steps before the onset, as the memorizing components are removed, at the same time as dₒᵤₜ narrows. So cleanup reduces the directions the outputs depend on, not only those the predictions depend on. Transformers that never grok narrow only slowly and stay two to nine times wider.
The final solution uses few directions
In the transformer, at the final checkpoint, d₀.₉₉ is 7.9% of the embedding’s directions (7.7 of 97), 6.8% of the MLP output weights (8.7 of 128) and 10.2% of the MLP input weights (13.0 of 128). The MLP block’s post-activations need only 3.4% (17 of 512). These counts are not inflated by the margin: dₒᵤₜ is roughly 6–13% of each of the weight matrices we analyse. Truncating to the leading directions keeps at least 99.26% of test accuracy, while random subspaces of the same rank keep at most 12.5%.
Judging truncation by accuracy can show an illusion of compression
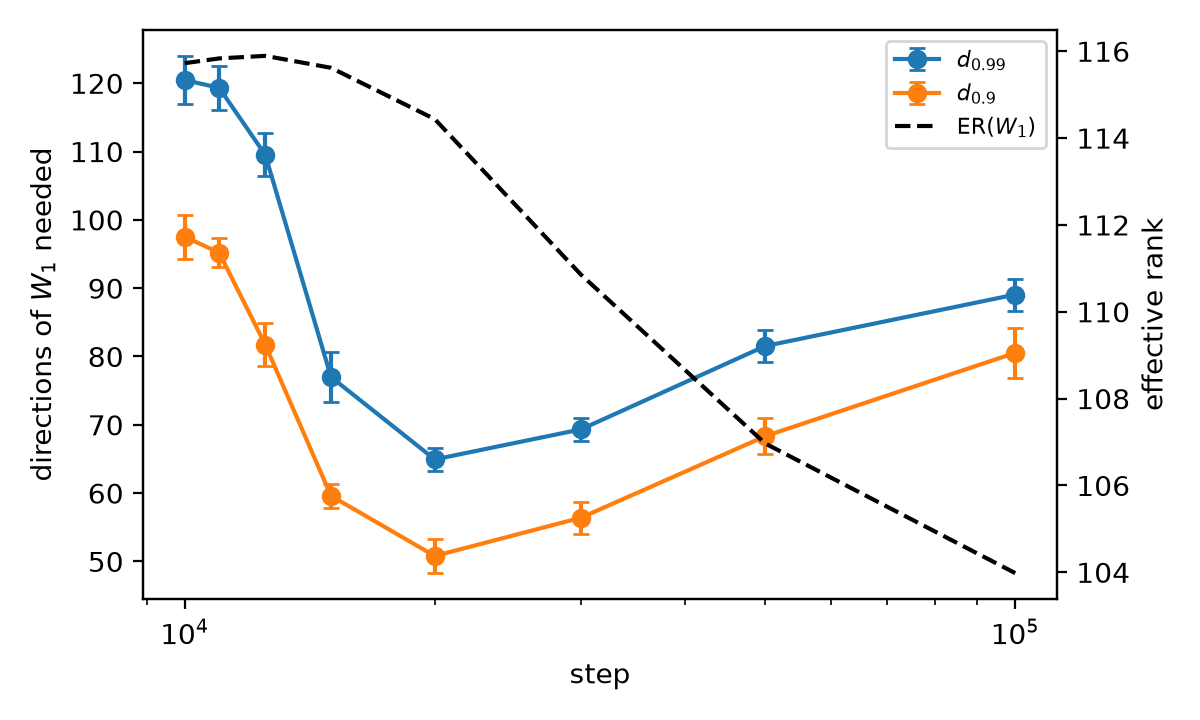
The MLP trained with mean-squared error shows why the counting rule matters. Its d₀.₉₉ narrows right after the onset, from 109.5 directions at step 12,500 to 64.9 at step 20,000, then widens again to 89.1. Over the same stretch the median margin grows more than fourfold, and dₒᵤₜ does not fall at all. It stays at 122–127 of 128. The apparent narrowing measured how far predictions were from flipping, not how many directions the function uses.
With cross-entropy, the MLP does crystallize, but late and as part of a different process. Its dₒᵤₜ stays near 120 around the onset and ends at 70–81, tracking the late fall in effective rank rather than the transition.
Why does the transformer crystallize further than the MLP?
We come think it comes down to the architecture. The transformer’s embedding uses about four Fourier frequencies, and each needs two directions, a cosine and a sine. That predicts about 8 directions, close to what the embedding, MLP output and unembedding keep (7.7–8.8). Attention also writes into almost the same directions the MLP block reads from, even in runs that never grok. So the MLP block only ever sees a few directions to begin with.
The MLP model has no such funnel. Its first layer reads both one-hot operands directly, so each frequency costs it four directions, and it spreads its weights over most of the 48 available frequencies. That leaves it little room to crystallize.
Finding 3: forcing low rank
We write a weight matrix as W = AB with inner dimension r and train from scratch. Every capped run is compared with a factorized control at full rank.
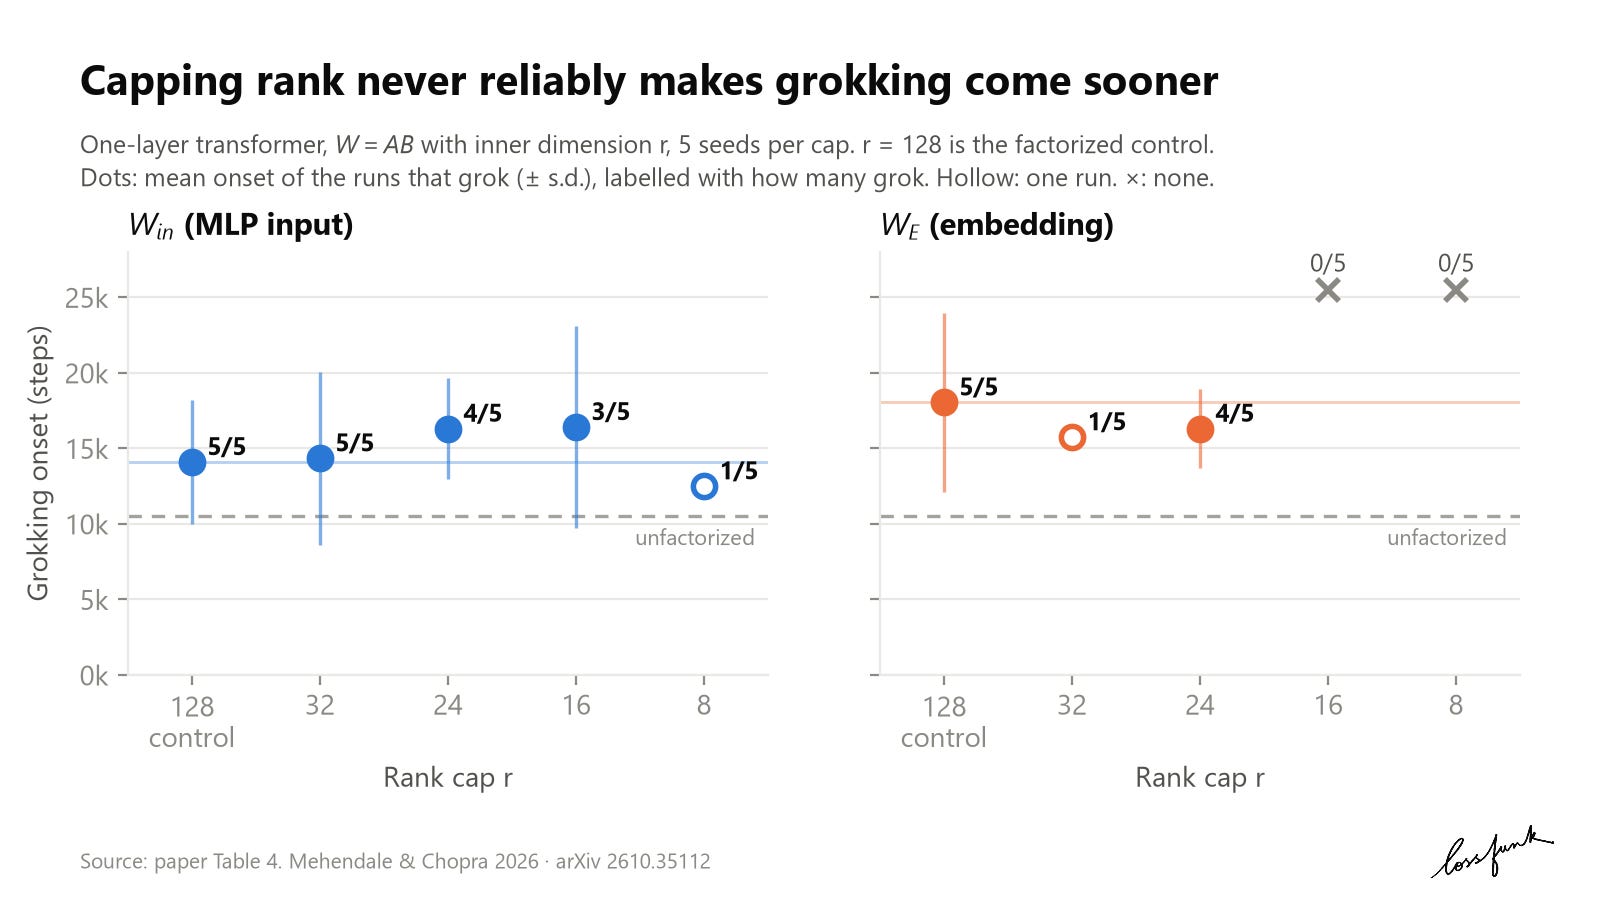
The trained solution needs only about 13 directions of the MLP block’s input weights and 8 of the embedding, so any cap above these leaves its capacity intact. Capping the input weights at 32 directions still doesn’t bring the onset forward and capping them at 24 or 16, delays grokking and makes it less reliable. Constraining them at 8 prevents grokking in four of five seeds. Capping the embedding is worse: only five of twenty capped runs grok.
Two known mechanisms are consistent with this. Factorizing preconditions the updates of the product (Arora et al., 2018), which can speed training up. And weight decay on A and B acts as a nuclear-norm penalty on W. That penalty is negligible at the MLP’s small weight decay but strong at the transformer’s, which fits one speeding up and the other slowing down.
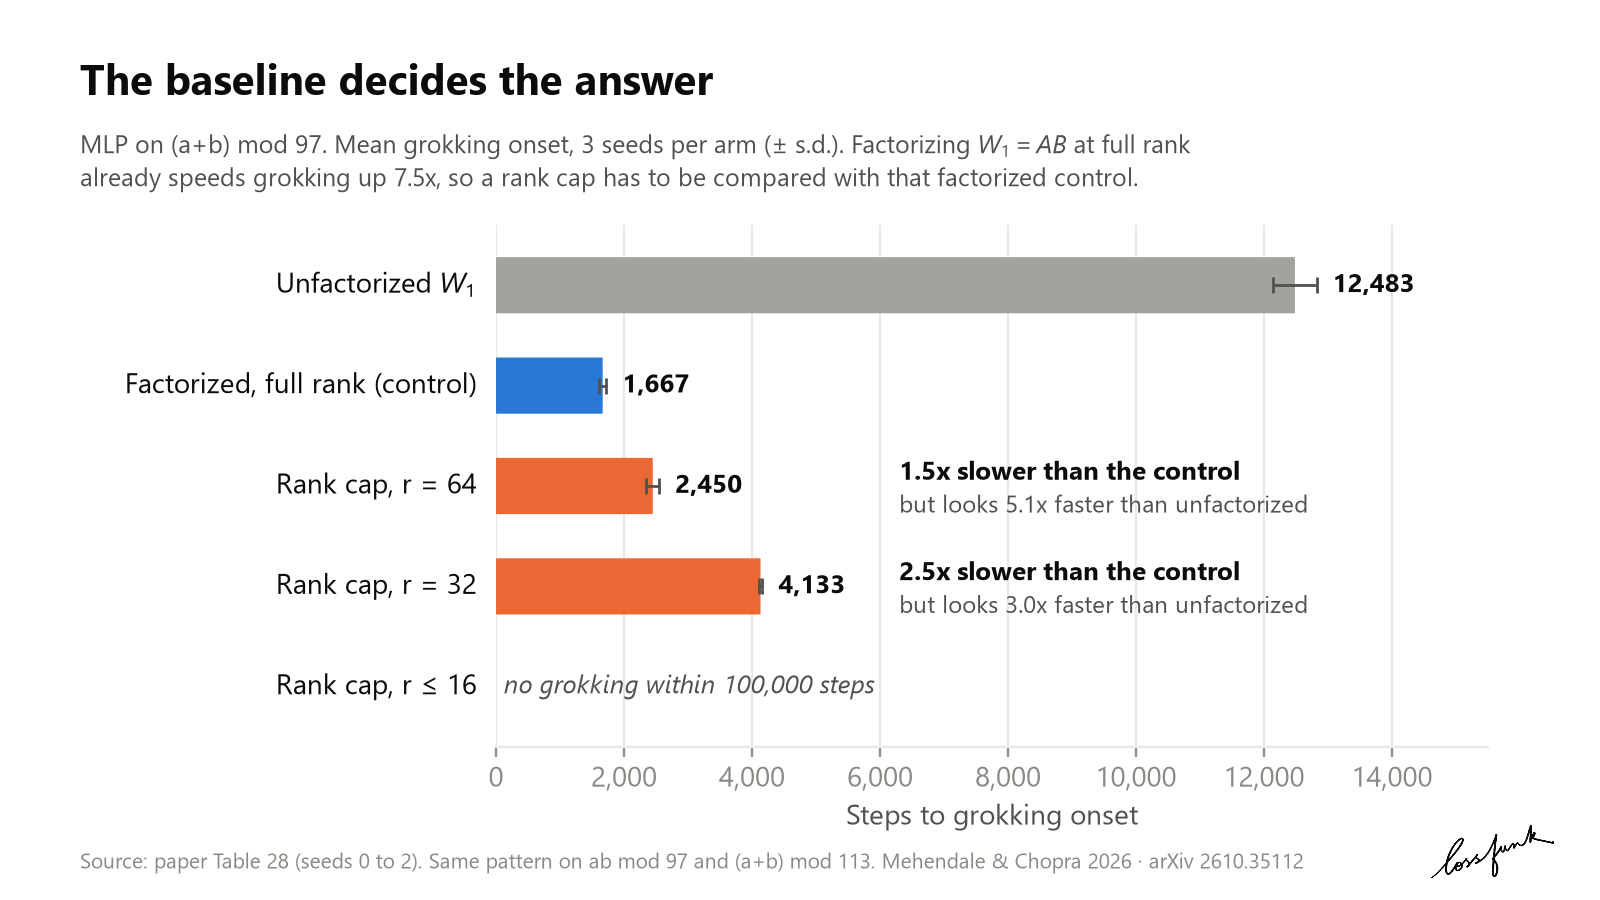
Against the factorized control, rank caps delay the MLP’s grokking. Against the unfactorized network, the same caps would look like they speed it up.
More findings
The MLP’s late compression is set by AdamW’s ε
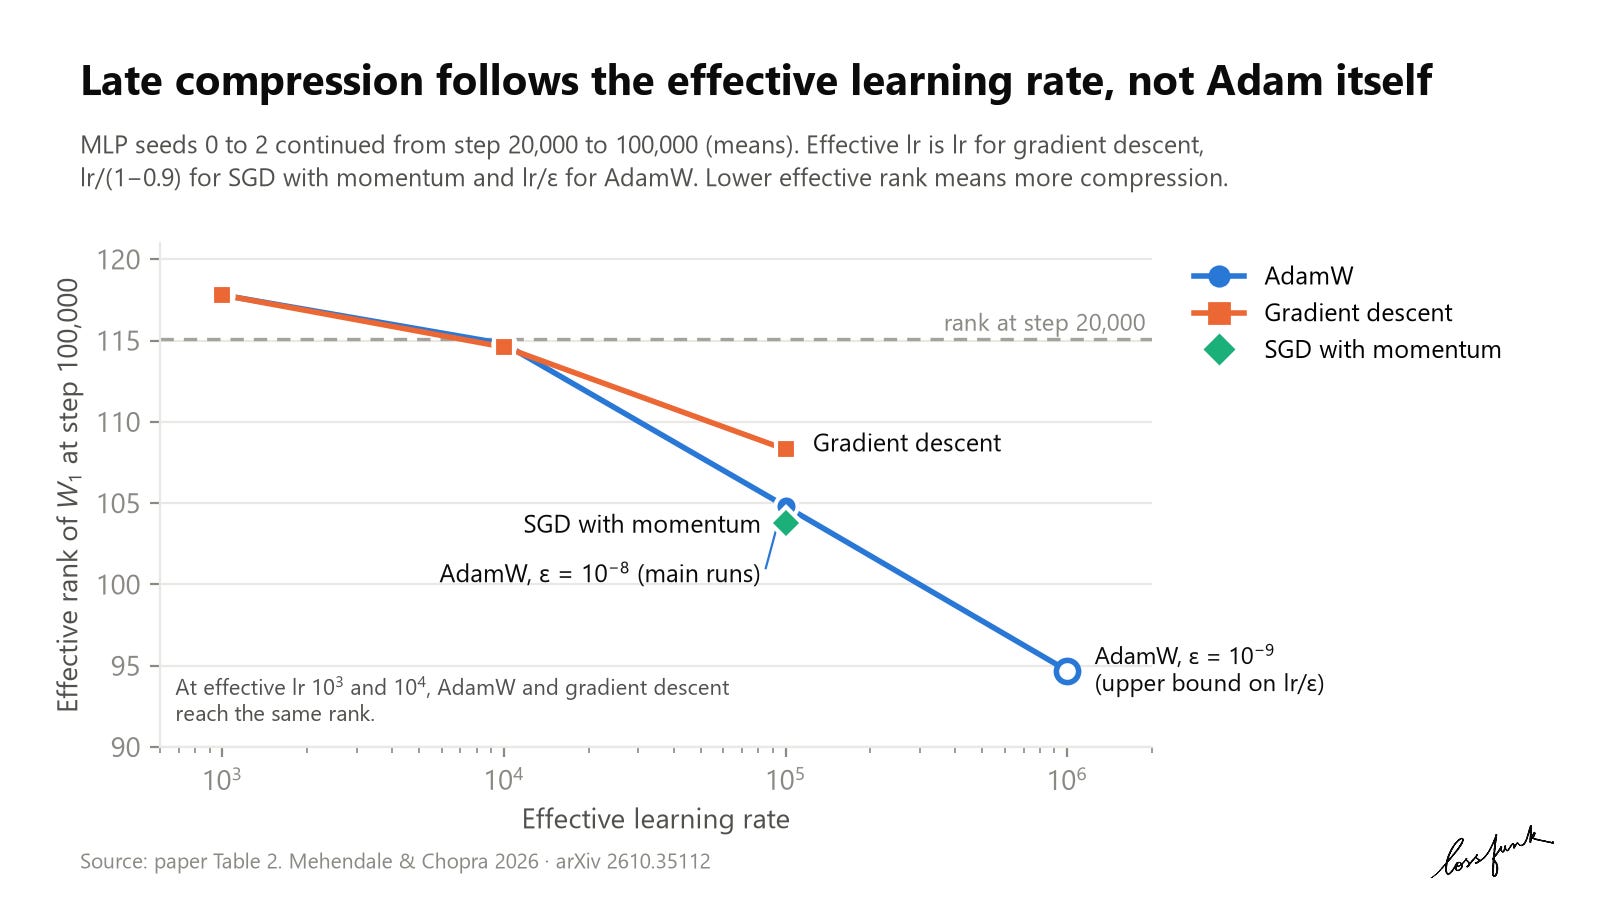
Late in training, the MLP’s gradients become so small that square root of Adam’s second-moment estimate falls below ε for 87–100% of coordinates. The update then behaves like m/ε, so AdamW acts as gradient descent with momentum at learning rate lr/ε = 10⁵. Continuing training with other optimizers confirms that this effective learning rate, not Adam itself, drives the late compression. SGD with momentum at the same effective rate reproduces all of it.
Concurrent work by Barron et al. (2026) reaches the same small-gradient regime from the cross-entropy side. There, the balance between Adam’s ε and weight decay sets the margin, at roughly log(1/ε).
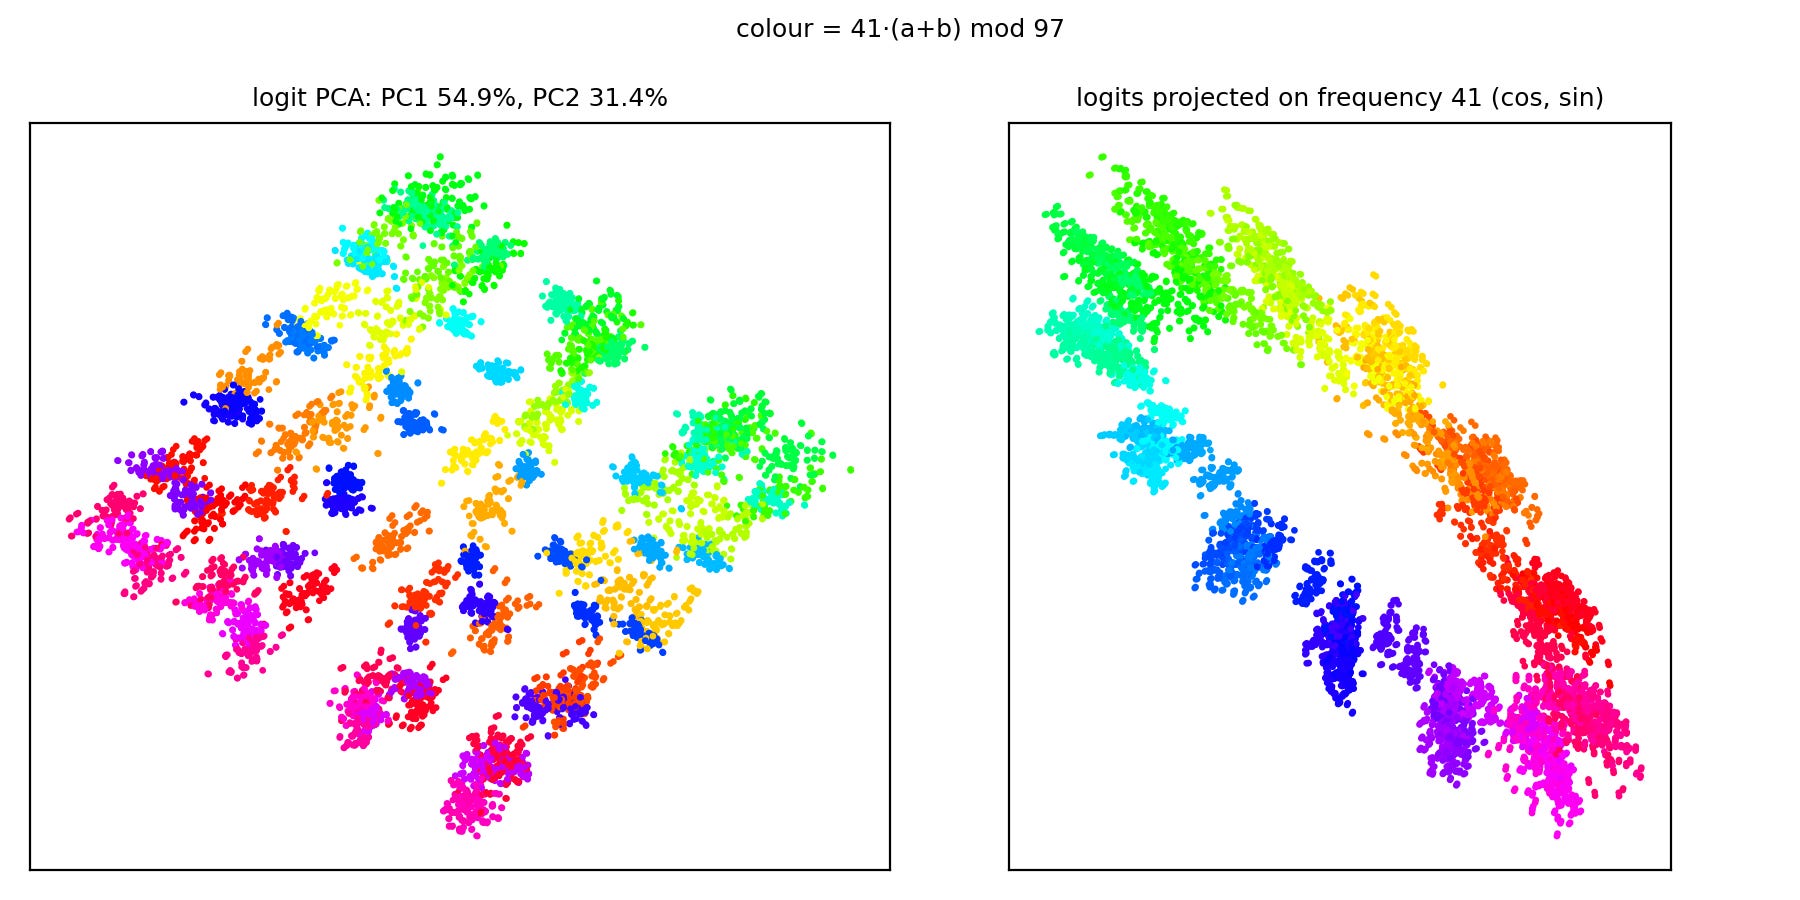
A separate result: different MLP seeds favour different Fourier frequencies, and their top weight subspaces overlap no more than random ones. Yet after an orthogonal Procrustes rotation, one seed’s readout decodes another seed’s hidden activations with 95.8% accuracy, against 1.0% without the rotation. The rotation does not rescue a network trained on random labels, or one grokked on a different task (0.7–1.4%).
Fourier IPR is not an early-warning signal
The Fourier inverse participation ratio, which measures how periodic the hidden units are, rises before the onset. But it also rises in every network that never groks: all five random-label MLPs and all seven non-grokking transformers. It tracks the progress of training rather than an impending transition.
Takeaways
Compression tracks the grokking onset, not memorization, and forcing low rank from initialization does not reliably bring grokking forward. Three results matter beyond grokking, for anyone who measures how many directions a network uses.
Judging truncation by accuracy can show an illusion of compression. In the MSE-trained MLP, d₀.₉₉ fell from 110 to 65 of 128 directions after the onset, while dₒᵤₜ stayed at 122–127. The narrowing was the margin growing. d₀.₉₉ later rose again to 89, so it is not even a fixed property of the trained model.
A rank cap is also a reparameterization, and the baseline flips the conclusion. Writing W = AB at full rank made the MLP grok 7.5x sooner on its own. Against the unfactorized network, rank caps look 3–5x faster. Against the factorized control, they are 1.5–2.5x slower.
Spectral signals need negative controls. Fourier IPR rose in all 5 random-label MLPs and all 7 transformers that never grokked, so it cannot flag an upcoming onset. Effective rank falls in those runs too, by 15–23% against 60% in runs that grok, and it drops early in every run as weight decay shrinks the random initialization. Only the comparison with controls separates the grokking signal from these.
My own hunch, which this paper does not test: delayed generalization is more common than it looks, just hard to observe. It has been found well beyond toy tasks, from image and text data to multi-hop reasoning and LLM pretraining. And once a network has memorized, that solution takes effort to get rid of. It reminds me of how people often memorize something before they understand it, though I would not push the analogy far. In our transformers, that “getting rid of” is visible: the subspace narrows at the same time as the memorizing components are cleaned up.
Limitations
All our tasks are modular arithmetic on cyclic groups. Non-abelian groups, and language or vision models, would test the results more broadly. The two architectures also differ in loss and training length. Granger tests capture only temporal order, so our causal conclusions rest on the rank interventions.